
AI agents get phished too. Check before they act.
AI agents are more phishable than people: they cannot smell a scam, they follow instructions hidden inside a page, and they act in milliseconds. Dralvia gives an agent a safety verdict before it visits a URL, enters credentials, pays, downloads, or connects a tool, then keeps a human in the loop for the actions that matter.
Agent security
See Dralvia in action.
Register agent context, run trust checks, and review connectors and requested actions.
- Register supported agent context
- Run a trust check
- Review connector and action evidence
This preview shows the Dralvia workspace. Sign in to see your own scans, alerts, and activity.
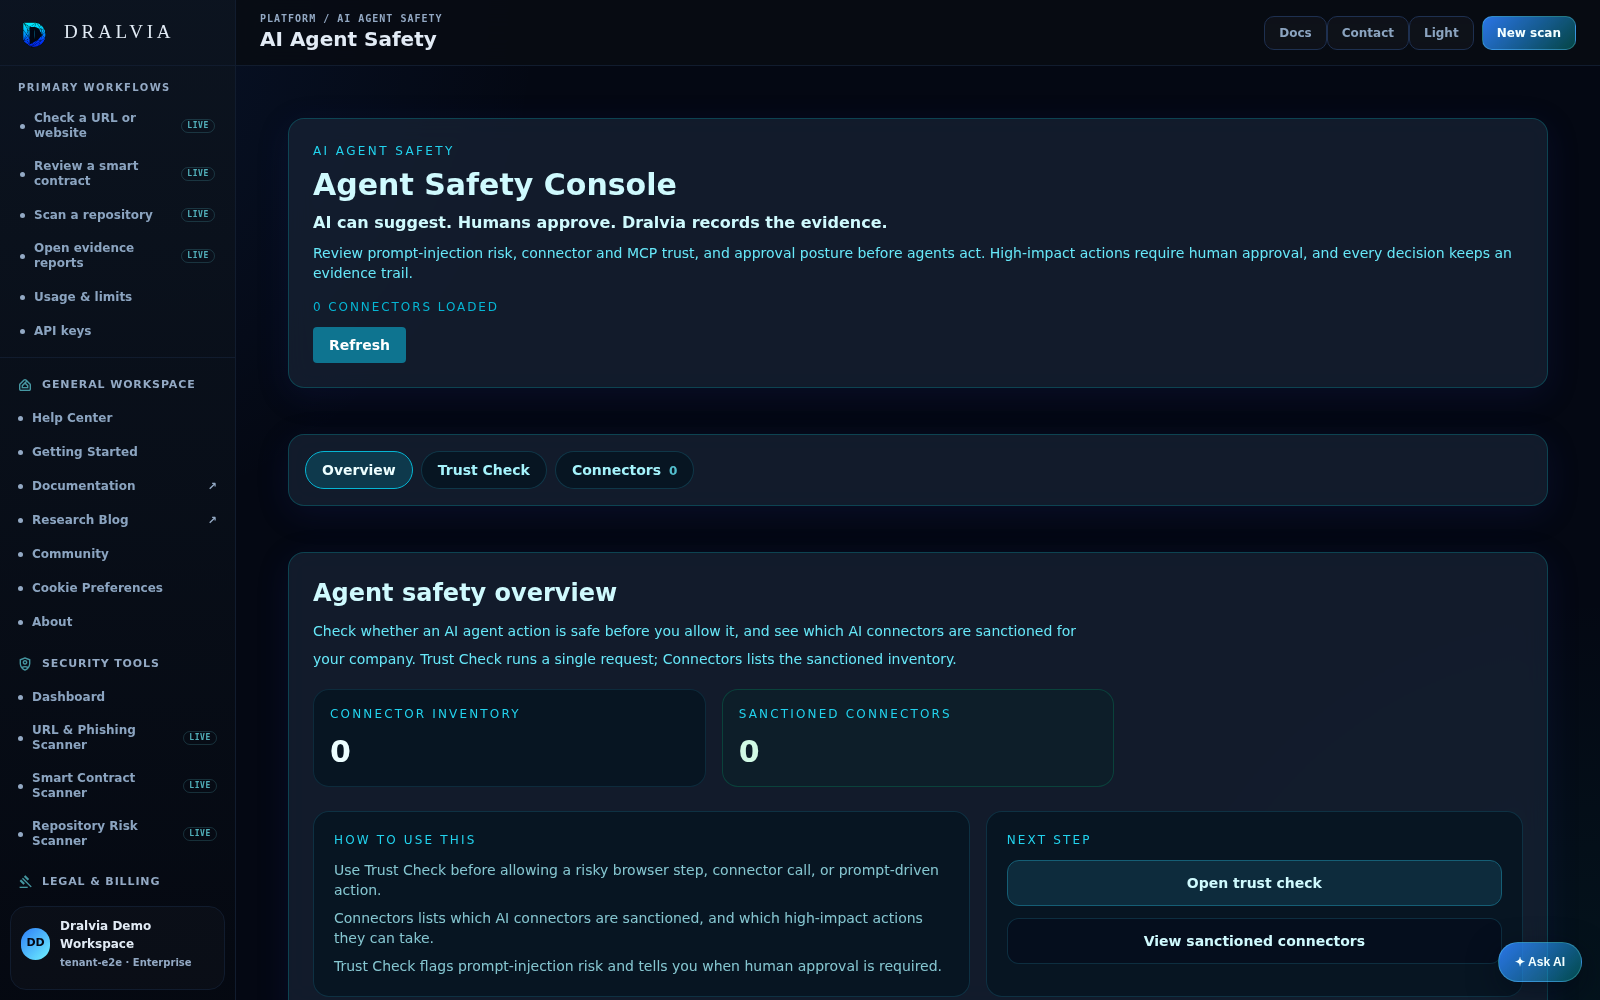
A checkpoint in front of risky actions.
Prompt-injection review
Flag suspicious or hidden instructions in AI assistance so a person can review before acting.
Connector governance
Connectors carry a sanctioned or unsanctioned status, so unapproved ones can be held back.
High-impact approval
Require explicit human approval before a high-impact action runs.
Second approver
Sensitive automation can require a second approver before it proceeds.
Decision trail
Approvals and decisions are recorded so they can be reviewed later.
Scoped to your workspace
Governance and approvals are scoped to your company workspace.
A safety check before every risky move.
The agent asks first
Before it visits a URL, enters credentials, pays, downloads, or connects a tool, your agent sends the destination and its intent to Dralvia.
Dralvia returns a verdict
Allow, approval needed, or block, with machine-readable reasons, the contributing risk flags, and an evidence record, in under two seconds.
The agent honors it
Proceed, pause for a human, or stop. Wire it in with plain REST or as a Model Context Protocol tool in minutes.
Purpose-built for how agents work.
Pre-action verdict
One call returns allow, approval needed, or block for the action the agent is about to take, with the destination reputation folded in.
Prompt-injection screen
Check page text or tool output for hidden instructions and tool-hijack patterns before the agent acts on it.
MCP-native
Both checks are tools on a Model Context Protocol server, so any MCP-capable agent can adopt them in minutes.
Explainable flags
Every signal is a named, weighted risk flag, so a verdict is never a black box.
Honest detection
Injection detection is measured against a labeled corpus with benign controls, so the numbers are real, not marketing.
No new bill
Checks meter as usage on your existing plan, with no separate billing surface to set up.
Browser-native AI usage control
Secure how your team uses AI: control data movement, detect sensitive content, and keep a human in the loop, with evidence on every decision.
 ChatGPT
Honest answers.
Agents cannot sense a scam the way a person can. They will follow instructions hidden in a page and act in milliseconds, which makes them easy to phish. A safety check before each risky action catches the bad destination or hidden instruction first.
Give your agent a safety check before it acts.
Add a pre-action verdict and a prompt-injection screen via REST or MCP, and keep a human in the loop for the actions that matter.